Eli Lifland
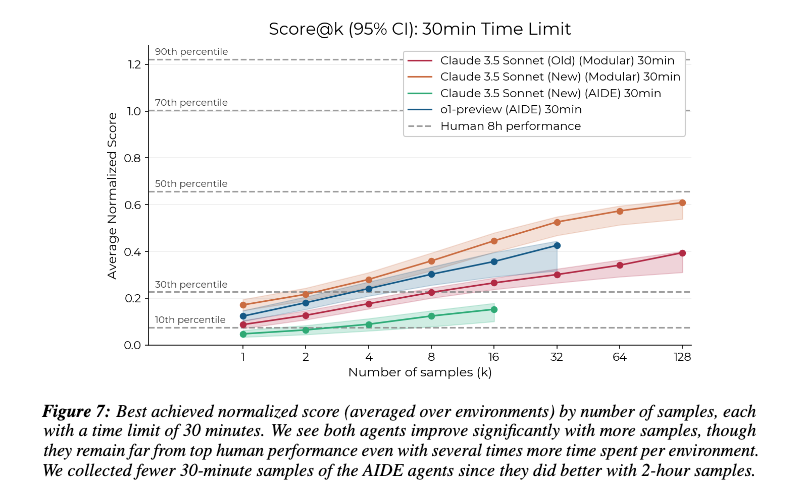
Takeaways re: AI R&D performance: 1. Claude 3.5 Sonnet reaches ~50th percentile human baseline 8-hour performance. 2. Sonnet Old-> New is a 0.2 jump in 4 months. We're 0.6 away from 90th percentile baselines. I think this significantly shortens my timelines. (caveats in reply)

METR
How close are current AI agents to automating AI R&D? Our new ML research engineering benchmark (RE-Bench) addresses this question by directly comparing frontier models such as Claude 3.5 Sonnet and o1-preview with 50+ human experts on 7 challenging research engineering tasks.