
Claude
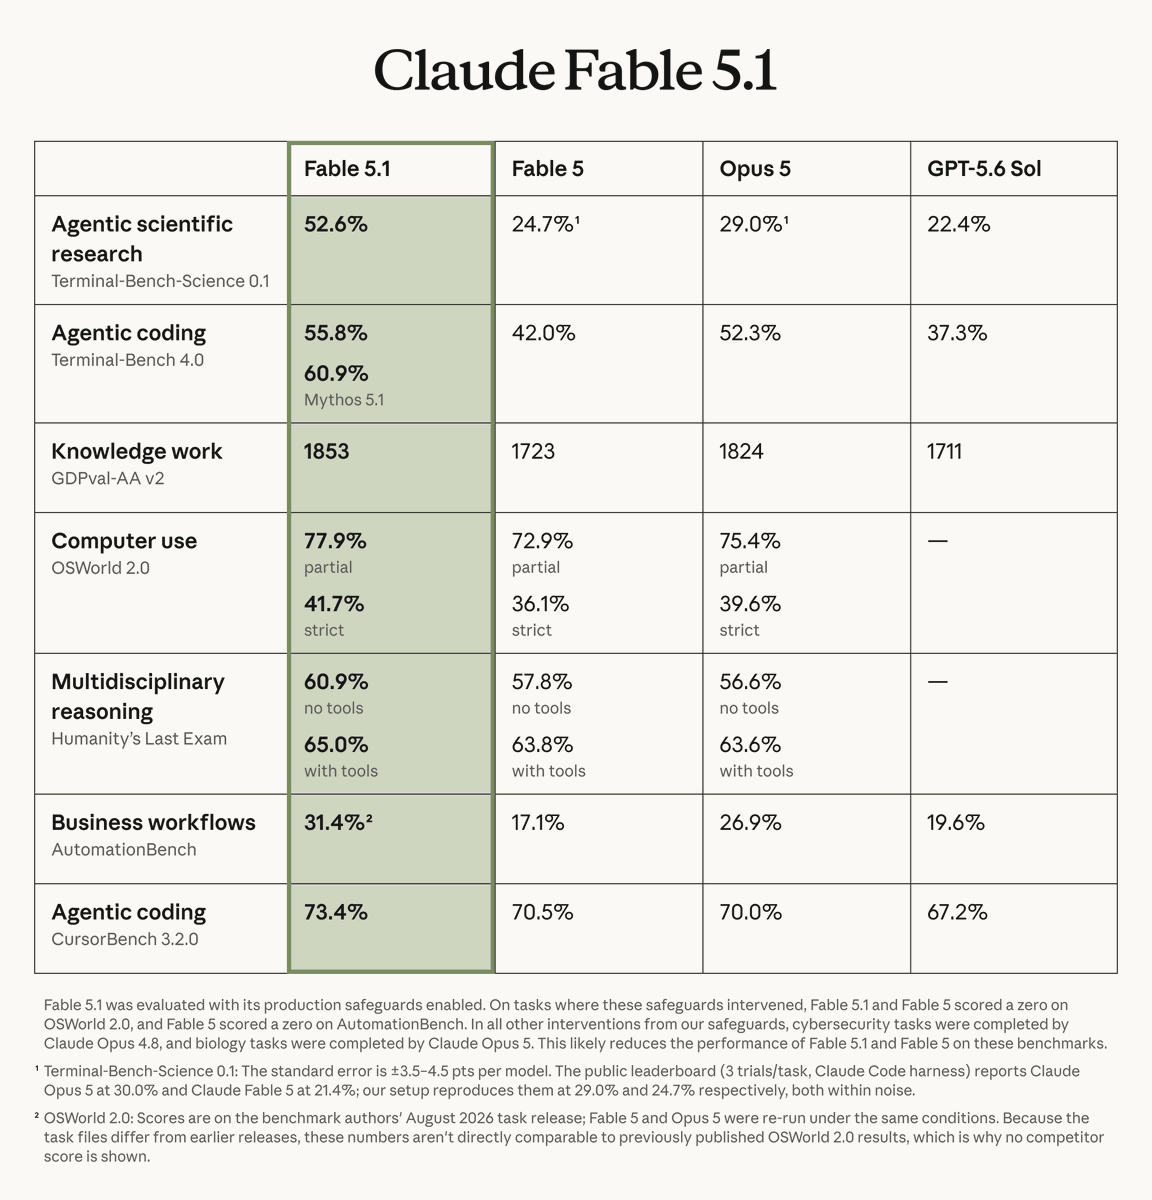
Across our benchmarks, the model sets a new standard. It scores 52.6% on Terminal-Bench-Science 0.1, more than double Fable 5. On Terminal-Bench 4.0, it scores 55.8% against 42.0% for Fable 5.
Claude
Across our benchmarks, the model sets a new standard. It scores 52.6% on Terminal-Bench-Science 0.1, more than double Fable 5. On Terminal-Bench 4.0, it scores 55.8% against 42.0% for Fable 5.