Eli Lifland
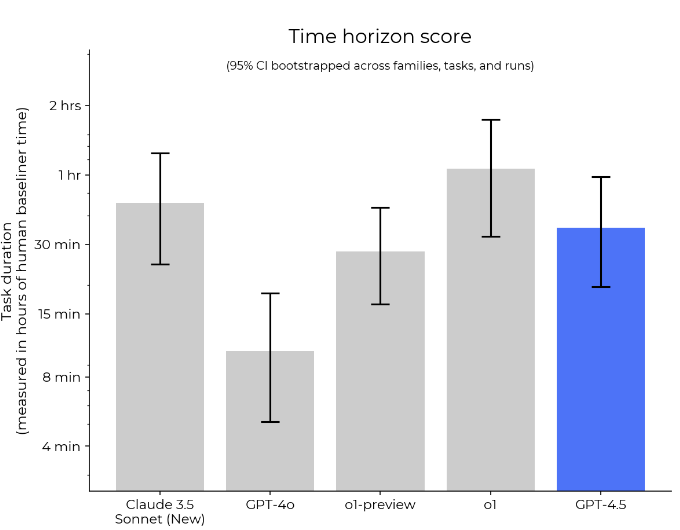
And now I lengthen my timelines, at least if my preliminary assessment of GPT-4.5 holds up. Not that much better than 4o (especially at coding, and worse than Sonnet at coding) while being 15x more expensive than 4o, and 10-25x more expensive than Sonnet 3.7. Weird.
Eli Lifland
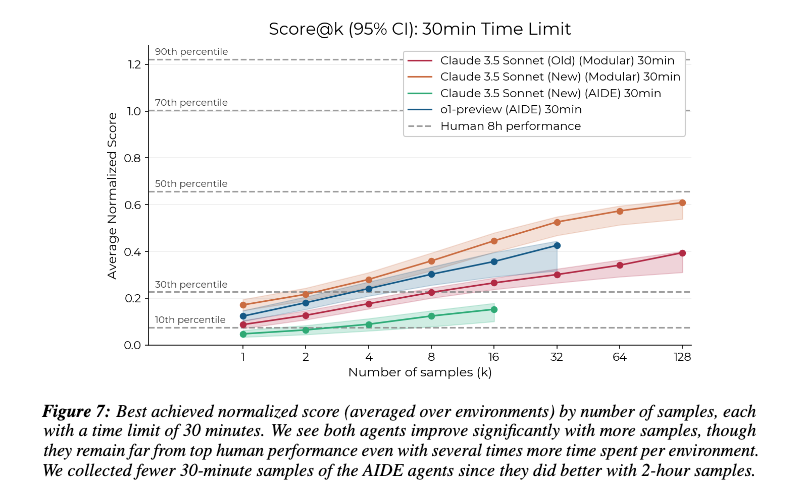
Takeaways re: AI R&D performance: 1. Claude 3.5 Sonnet reaches ~50th percentile human baseline 8-hour performance. 2. Sonnet Old-> New is a 0.2 jump in 4 months. We're 0.6 away from 90th percentile baselines. I think this significantly shortens my timelines. (caveats in reply)